
OpenBMB built MiniCPM5-2B for local assistants, coding agents, tool-use loops, and short reasoning jobs where a compact model is the point. It is a dense 2.52B LlamaForCausalLM checkpoint (~5 GB BF16), English and Chinese, native 131,072-token context, Apache 2.0. Stock Llama architecture: vLLM loads it without a plugin.
That is a different renter than a 70B. You are not hunting H100s. You are standing up an OpenAI-style endpoint for chat, a coding agent, or a batch of extracts, and you need to know which Massed Compute SKU to click.
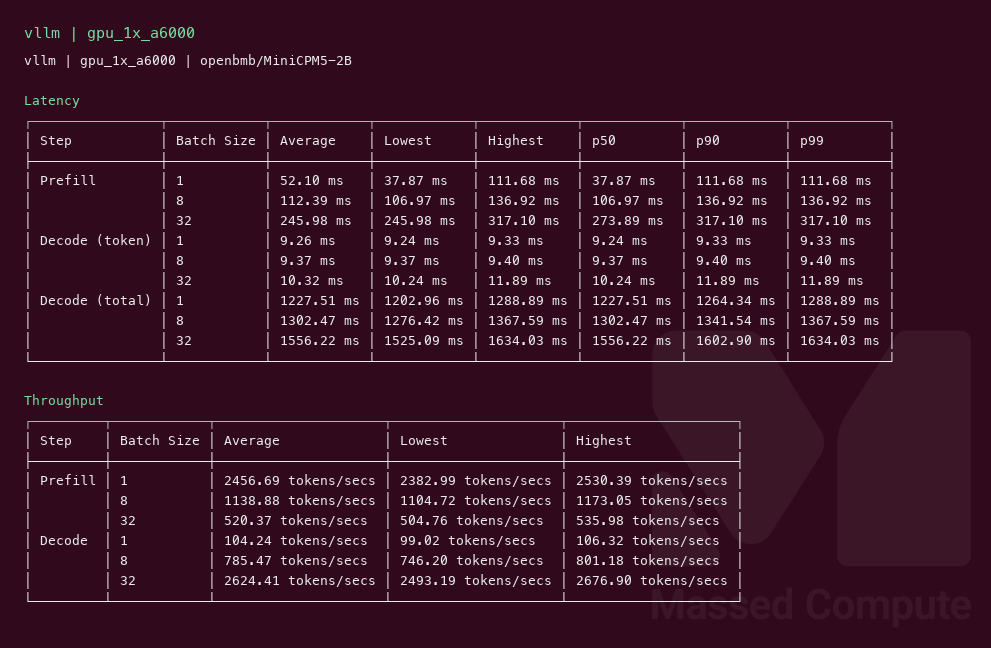
We served the exact openbmb/MiniCPM5-2B BF16 weights on three cards. Packed output token throughput at concurrency 32: A6000 is 2624.4 tok/s at $0.57/hr ($0.060 per million output tokens). Blackwell is 5783.3 tok/s and 61.9 ms first token at $2.19/hr. L40S sits in the middle and wins neither job.
If the product is a queue, rent A6000. If a person or an agent is sitting on the first token, rent Blackwell.
Live list rates on 16 September 2026 still match the 14 September capture: A6000 $0.57/hr, L40S $0.97/hr, RTX PRO 6000 Blackwell $2.19/hr. L40S moved from $0.88 to $0.97 on 8 September 2026. Confirm current GPU pricing before you launch. Full method and showcases: MiniCPM5-2B GPU bench.
What this model is for
OpenBMB’s own brief: local assistants, coding agents, tool-use workflows, and reasoning, with long context kept in a small footprint. They position it as 2B-class open-source SOTA and competitive with some 4B models on coding, math, long-context, tool use, and agent tasks. That is their card, not our bench. Our numbers are packed vLLM text decode.
Practical jobs this size actually gets rented for:
Packed chat API. Many concurrent sessions, OpenAI-compatible /v1/chat/completions, bilingual EN/ZH support or an internal assistant. Throughput per dollar is the product. A6000.
Coding agent / copilot loop. Repeated round trips: read a file, propose a patch, run a tool, try again. Ten hops on A6000 spend ~2.7 s just waiting for first token (10 × 273.9 ms). Same ten hops on Blackwell are ~0.62 s (10 × 61.9 ms). Pay Blackwell when a human is in that loop.
Tool-calling / function-calling agents. MiniCPM5-2B emits XML-style tool calls. OpenBMB recommends SGLang with --tool-call-parser minicpm5 for OpenAI tool_calls. Our ladder is vLLM text decode, not a tool-call benchmark. Use the SKU guidance (A6000 for a queue of agents, Blackwell when each hop is attended). Do not read 2624.4 tok/s as measured tool-call speed.
Batch extract, classify, summarize. Nightly JSON extraction, ticket tagging, log summarization. Nobody is watching the spinner. A6000 at $0.060 / 1M output tokens.
Long documents (native 128k). The checkpoint supports 131,072 tokens. We served --max-model-len 8192 and timed random 128/128. Do not treat these tok/s as a 128k bench. Longer context will move TTFT and tok/s. Untested here.
Not this model. This is not MiniCPM-V and not MiniCPM-Robot. No image generation, no robot manip/track. Text in, tokens out.
| Use case | What you are buying | Card |
|---|---|---|
| Many concurrent chats / internal assistant | Packed output tok/s per dollar | A6000 |
| Unattended batch extract / classify / summarize | $/1M output tokens | A6000 |
| Interactive copilot or attended agent | First token + tok/s while someone waits | Blackwell |
| Tool loop with a human watching | Median TTFT across many hops | Blackwell |
| “Middle” upgrade because L40S is 48 GB | Nothing this job needs | Skip L40S |
| 128k context, vision, robot, SGLang tools | Not this table | Not measured |
What we measured (and what we did not)
Pinned profile: random prompts, input 128, output 128, request-rate inf, concurrency 1 / 8 / 32. Headlines are c32 output token throughput. Engine: vLLM vllm/vllm-openai:nightly digest sha256:78c73c96fb74cdbee0f6d90d8ba756540a2385668a35f565f73dbab1da461099, --max-model-len 8192 --gpu-memory-utilization 0.92 --max-num-batched-tokens 16384 --kv-cache-dtype fp8. No prefix-caching. Exact BF16. Capture 14 September 2026.
Not in this table: 128k context, SGLang tool parser, DSpark speculative decode, GGUF/Ollama/MLX on-device, image input.
The numbers
| SKU | List $/hr | Output tok/s (c32) | TTFT median | tok/s per $ | $/1M output tokens |
|---|---|---|---|---|---|
| RTX A6000 48GB | $0.57 | 2624.4 | 273.9 ms | 4604 | $0.060 |
| L40S 48GB | $0.97 | 3244.9 | 124.7 ms | 3345 | $0.083 |
| RTX PRO 6000 Blackwell 96GB | $2.19 | 5783.3 | 61.9 ms | 2640 | $0.105 |
Least expensive SKU we launched is gpu_1x_a6000. Mid is gpu_1x_l40s. Premium is gpu_1x_pro_6000_blackwell. On the capture date A30 ($0.35, 24 GB) was live and not launched. gpu_1x_a6000_spot ($0.50) and gpu_1x_a6000_low_ram ($0.55) were not launched. Those cheaper SKUs are untested. Do not read A6000 as cheapest-fit.
A6000 is the value card. Blackwell is the speed card. Those two winners are not the same GPU.
What extra money buys on L40S
L40S is 23% faster than A6000 (3244.9 vs 2624.4 tok/s). It costs 70% more per hour ($0.97 vs $0.57). Tokens per dollar fall from 4604 to 3345. Cost per million output tokens rises from $0.060 to $0.083. Median first token drops from 273.9 ms to 124.7 ms, which is the only argument for L40S, and Blackwell then halves that again to 61.9 ms. Skip L40S for this model.
What extra money buys on Blackwell
Blackwell is 2.2× A6000 and 1.7× L40S on packed output tok/s. The hourly is 3.8× A6000. Tokens per dollar are the worst of the three. First token is the real purchase: 273.9 ms → 61.9 ms.
Around 100 ms after send reads as instant. Past a quarter second, people notice they are waiting. A packed chat API does not care. A coding agent with a human in the loop does.
The 2.52B BF16 weights are about 5 GB. They fit 24 GB. nvidia-smi while the server was up held 43.75 GiB on A6000, 41.12 GiB on L40S, and 87.77 GiB on Blackwell (MiB / 1024). That reservation is vLLM filling --gpu-memory-utilization 0.92, not a fit requirement.
vLLM nightly on A6000, c32 2624.4 output tok/s, TTFT median 273.9 ms:
vLLM nightly on Blackwell, c32 5783.3 output tok/s, TTFT median 61.9 ms:

Pick the card from the job
| Workload | Speed winner | Value winner | When premium is justified | When premium is waste |
|---|---|---|---|---|
| Packed chat API / many sessions | Blackwell, 5783.3 tok/s | A6000, $0.060 / 1M out | Queue is tok/s-bound and 2624.4 tok/s is the bottleneck | Dollars per token, overnight batch |
| Attended coding agent | Blackwell, 61.9 ms TTFT | A6000 still wins $/token | Human or agent waiting on each hop | Unattended CI that can wait 274 ms |
| Tool-calling workers (vLLM text path) | Blackwell on wait | A6000 on fill | Interactive tools | Background tool farm |
| L40S as a “middle” 48 GB card | — | — | Never for this table | Always skip |
How to launch
- Sign in to the Massed Compute marketplace and open Deploy.
- Pick
gpu_1x_a6000for a chat API or batch. Takegpu_1x_pro_6000_blackwellonly if first token is the product. Do not pickgpu_1x_l40sfor this job. - Choose an Ubuntu image with NVIDIA drivers.
- Add your SSH key. Launch. Serve
openbmb/MiniCPM5-2Bwith vLLM for a plain OpenAI server, or SGLang if you need the MiniCPM5 tool-call parser.
Pay only for the hours you use. Confirm the live rate on GPU pricing at launch. The three SKUs in this article were the ladder we ran on 14 September 2026.
Frequently Asked Questions
01What do people actually use MiniCPM5-2B for?
Local-style assistants, coding agents, tool loops, and compact reasoning. English and Chinese. Native 128k context on the card; our serve was 8k.
02Which GPU should I rent?
A6000 for packed serving and batch. Blackwell when a person is waiting on first token. Skip L40S.
03Do I need Blackwell for a chat API?
No. Exact BF16 on A6000 is 2624.4 output tok/s and $0.060 per million output tokens. Blackwell is 5783.3 tok/s and loses on tokens per dollar.
04When is Blackwell worth it?
Interactive copilot or an attended agent. Ten round trips waste ~2.7 s of first-token wait on A6000 vs ~0.62 s on Blackwell.
05What does L40S buy?
Not enough. +23% output tok/s for +70% $/hr. First token is better than A6000 and still worse than Blackwell.
06Was this a 128k bench?
No. Native context is 131,072. We pinned --max-model-len 8192 and random 128/128 at c32.
07Did you quantize it?
No. Exact BF16 on every SKU. KV cache was fp8.
08vLLM or SGLang?
Numbers are vLLM. OpenBMB recommends SGLang for tool calling (--tool-call-parser minicpm5). We did not time that path.
09Is this MiniCPM-Robot or MiniCPM-V?
No. openbmb/MiniCPM5-2B text decode only.
10Is A6000 the cheapest card that can run it?
Unknown. A30 ($0.35), A6000 spot ($0.50), and A6000 low-RAM ($0.55) were live and not launched. A6000 is the least expensive SKU we ran.
Deploy MiniCPM5-2B GPU Guide: Chat APIs, Coding Agents, and Which Card to Rent
Launch NVIDIA L40 instances optimized for OpenAI-compatible inference. Get 48GB VRAM, blazing-fast NVMe storage, and per-second billing.
Think it. Build it. Scale it.