-

Do You Need Blackwell for Spark-X2.5-4B and MiniMax-H3 Turbo?
A6000 wins dollars for Spark-X2.5-4B packed serving and MiniMax-H3 Turbo clips. Blackwell is the speed card. L40S is the skip.
-
How Far Generative AI Has Come
Same burning-ships prompt from Disco Diffusion to Flux and LTX-2.5, images and clips, all on one rented GPU.
-
Train Large Models with DeepSpeed on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× H100, install DeepSpeed, and ZeRO-train Qwen2.5. 0.5B DDP/ZeRO-2/ZeRO-3, 7B one-GPU baseline then ZeRO-3, checkpoint on disk.
-
Deploy NVIDIA Dynamo for Distributed LLM Inference (2026 Guide)
Launch a Massed Compute 2× RTX PRO 6000 Blackwell, pull NVIDIA Dynamo 1.4.1, and serve OpenAI /v1. Aggregated GPU0, then disaggregated prefill/decode over NIXL.
-
Fine-Tune LLMs with LLaMA-Factory on GPU Cloud (2026 Guide)
Launch a Massed Compute L40, install LLaMA-Factory, and QLoRA-tune Qwen2.5-0.5B-Instruct from YAML. CLI, WebUI, adapter on disk.
-
RL Post-Training with verl on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× A100, install verl, and GRPO-train Qwen2.5-0.5B-Instruct on GSM8K. 1-GPU baseline, 2-GPU FSDP+vLLM, checkpoint on disk.
-
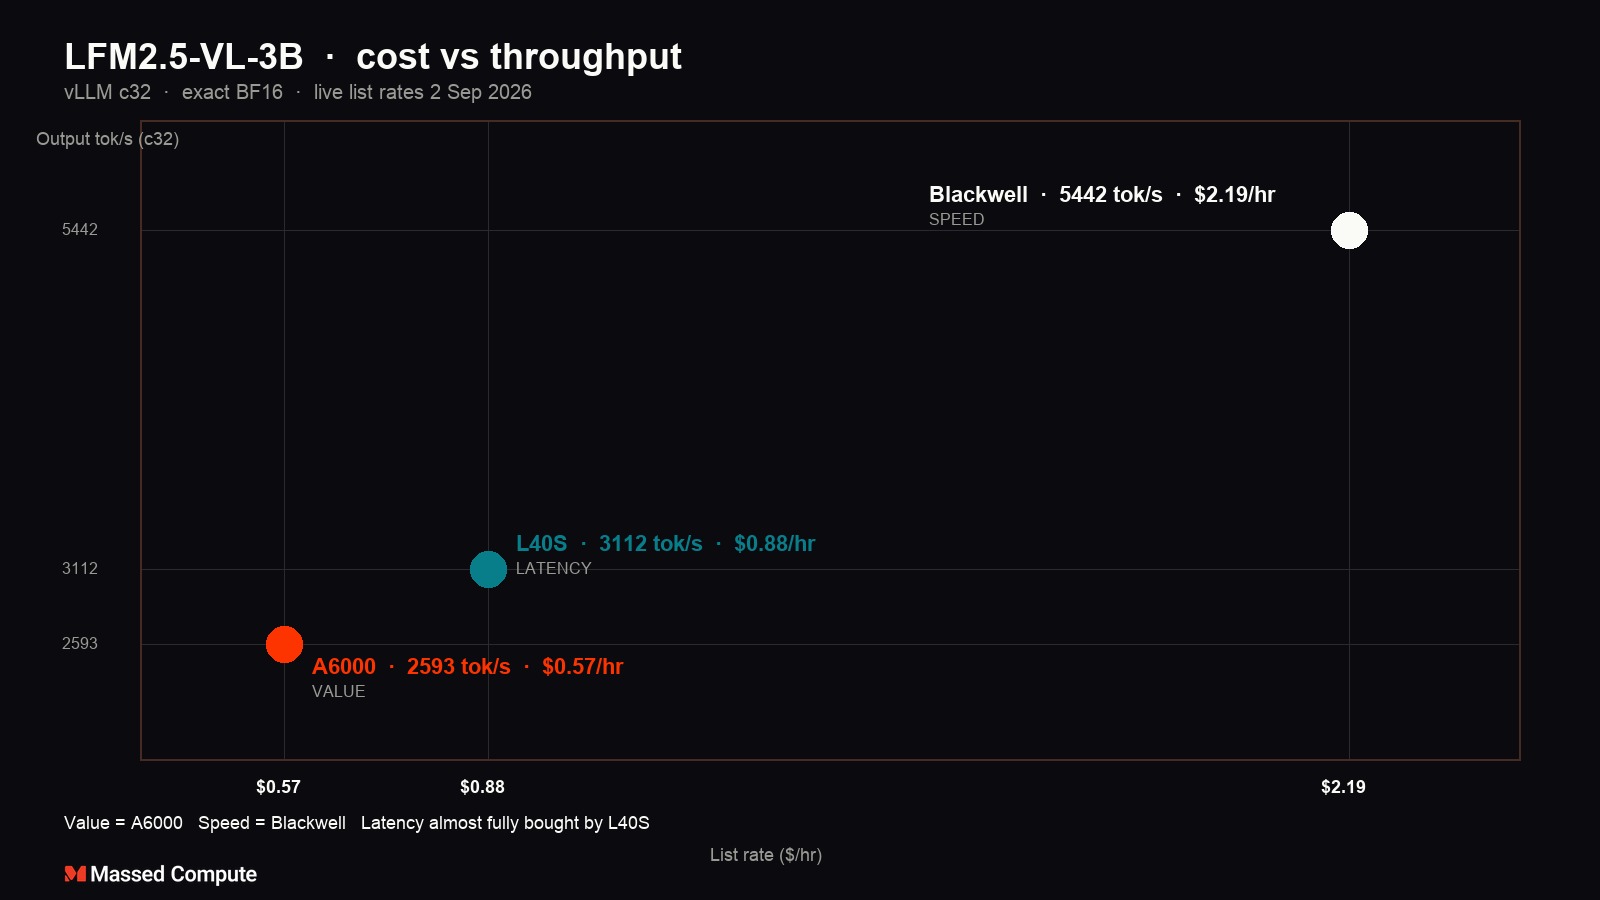
Do You Need Blackwell for LFM2.5-VL-3B?
A6000 wins dollars per token for LiquidAI LFM2.5-VL-3B at $0.57/hr. L40S buys latency. Blackwell is speed, not value.
-

Fine-Tune LLMs with Axolotl on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× H100, install Axolotl, and QLoRA-tune Qwen2.5-0.5B-Instruct from one YAML. Single-GPU baseline, 2-GPU torchrun, adapter on disk.
-
What Does It Really Take to Scale Enterprise AI?
Taking an AI project from concept to production is notoriously difficult. Most enterprise teams hit a wall along the way, either watching costs spiral out of control, wading through unexpected…
-
Run Hermes Agent with a Self-Hosted LLM on NVIDIA GPUs (2026 Guide)
Self-host Hermes Agent on a Massed Compute RTX PRO 6000 Blackwell with a local Ollama Llama 3.1 70B endpoint. Loopback /v1, UFW, Kanban swarm.
-

Deploy OpenClaw with a Private Local LLM on GPU Cloud (2026 Guide)
Self-host OpenClaw on a Massed Compute L40 with a local Ollama model. Loopback bind, UFW, nginx auth gate, and a real agent tool workflow.
-

Fine-Tune LLMs Faster with Unsloth on GPU Cloud (2026 Guide)
Launch a Massed Compute L40, install Unsloth, and QLoRA-tune Qwen2.5-0.5B-Instruct on Alpaca. Adapter export, VRAM, wall-clock.
Post Tags
a100 a6000 agents AI AI agents AI in business AI infrastructure AI training blackwell cloud computing Cloud GPU cost optimization data centers Disco Diffusion Enterprise AI fine tuning generative AI GPU GPU architecture GPU benchmarks h100 Hugging Face inference l40 l40s lfm Llama LLM lora machine learning minicpm multi gpu neocloud NVIDIA NVLink ollama qlora RAG research & HPC sglang training tutorial ubuntu VFX vllm
Article Categories
AI AutoGen Cloud GPU & Infrastructure Company News Data Analytics How To Hugging Face LLM NVIDIA Ollama Open Source Recipes Uncategorized VFX