-
How to Prevent Your Proprietary Data from Training Someone Else’s AI
Every interaction with an artificial intelligence system can create value. Prompts reveal what users need. Corrections reveal where models are wrong. Uploaded documents provide specialized information, and repeated workflows show…
-
Which GPU for a 7 GB 27B, and which GPU for a ticket router
Ternary Bonsai 2 decoded at 66.7 tok/s on an A6000. Laya classified a four-question ticket in 14.3 ms on an L40S. Pick the card for the job.
-

NVIDIA H100 SXM5 Use Cases, Pricing, and When to Launch 1x or 8x
Launch 1x or 8x NVIDIA H100 SXM5 on Massed Compute for 70B-class serve, long context, and NVLink train. 1x is $2.89/hr as of 16 September 2026.
-

MiniCPM5-2B GPU Guide: Chat APIs, Coding Agents, and Which Card to Rent
OpenBMB MiniCPM5-2B is a 2.5B local-assistant and coding-agent model. On Massed Compute, A6000 wins packed-serve dollars. Blackwell wins first token. L40S is the skip.
-

Do You Need Blackwell for Spark-X2.5-4B and MiniMax-H3 Turbo?
A6000 wins dollars for Spark-X2.5-4B packed serving and MiniMax-H3 Turbo clips. Blackwell is the speed card. L40S is the skip.
-
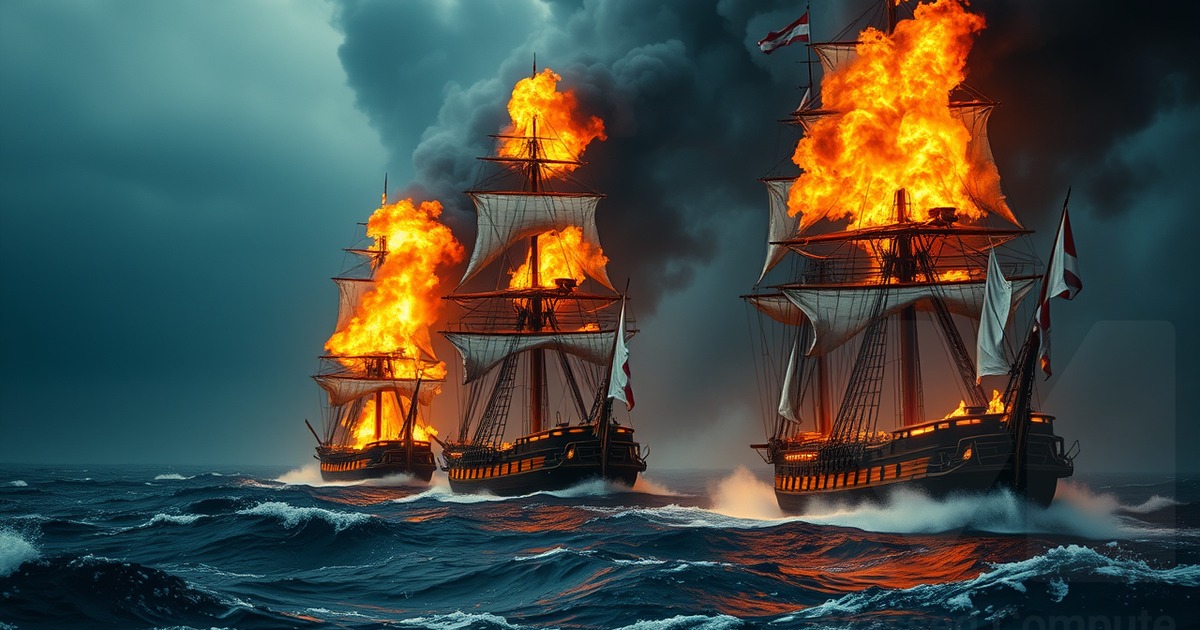
How Far Generative AI Has Come
Same burning-ships prompt from Disco Diffusion to Flux and LTX-2.5, images and clips, all on one rented GPU.
-
Train Large Models with DeepSpeed on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× H100, install DeepSpeed, and ZeRO-train Qwen2.5. 0.5B DDP/ZeRO-2/ZeRO-3, 7B one-GPU baseline then ZeRO-3, checkpoint on disk.
-
Deploy NVIDIA Dynamo for Distributed LLM Inference (2026 Guide)
Launch a Massed Compute 2× RTX PRO 6000 Blackwell, pull NVIDIA Dynamo 1.4.1, and serve OpenAI /v1. Aggregated GPU0, then disaggregated prefill/decode over NIXL.
-
Fine-Tune LLMs with LLaMA-Factory on GPU Cloud (2026 Guide)
Launch a Massed Compute L40, install LLaMA-Factory, and QLoRA-tune Qwen2.5-0.5B-Instruct from YAML. CLI, WebUI, adapter on disk.
-
RL Post-Training with verl on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× A100, install verl, and GRPO-train Qwen2.5-0.5B-Instruct on GSM8K. 1-GPU baseline, 2-GPU FSDP+vLLM, checkpoint on disk.
-
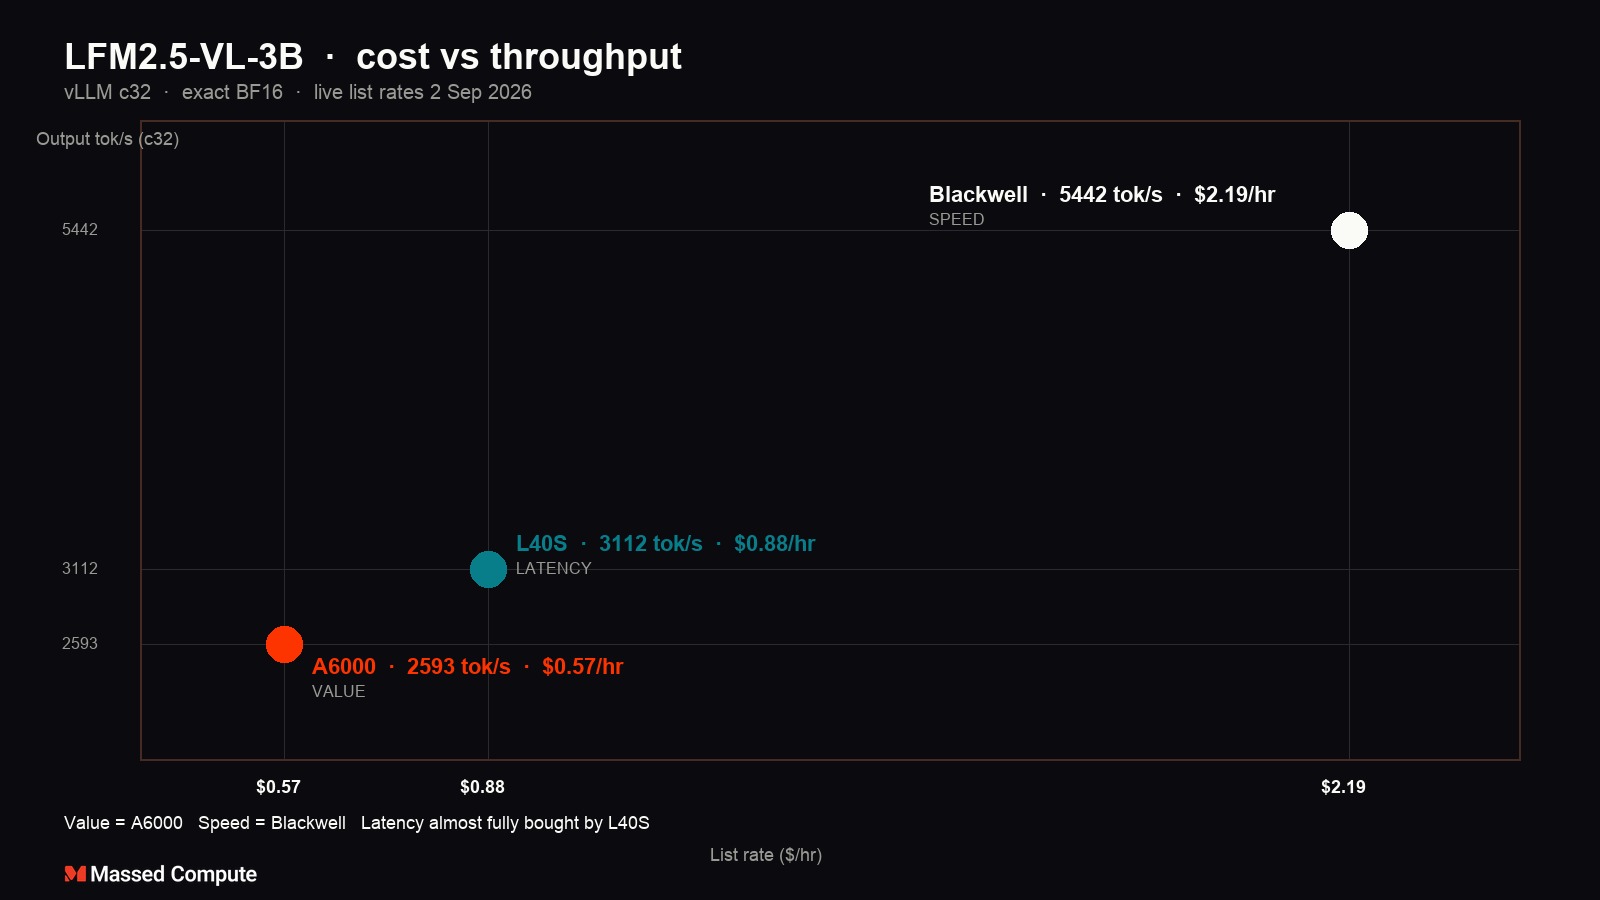
Do You Need Blackwell for LFM2.5-VL-3B?
A6000 wins dollars per token for LiquidAI LFM2.5-VL-3B at $0.57/hr. L40S buys latency. Blackwell is speed, not value.
-

Fine-Tune LLMs with Axolotl on Multi-GPU VMs (2026 Guide)
Launch a Massed Compute 2× H100, install Axolotl, and QLoRA-tune Qwen2.5-0.5B-Instruct from one YAML. Single-GPU baseline, 2-GPU torchrun, adapter on disk.
Post Tags
a6000 agents AI AI agents AI in business AI infrastructure AI training blackwell cloud computing Cloud GPU cost optimization data centers Enterprise AI fine tuning generative AI GPU GPU architecture GPU benchmarks h100 Hugging Face inference l40 l40s Llama LLM lora LTX machine learning minicpm multi gpu neocloud NVIDIA ollama pytorch qlora RAG research & HPC sglang SXM5 training tutorial ubuntu VFX vllm zero
Article Categories
AI AutoGen Cloud GPU & Infrastructure Company News Data Analytics How To Hugging Face LLM NVIDIA Ollama Open Source Recipes Uncategorized VFX